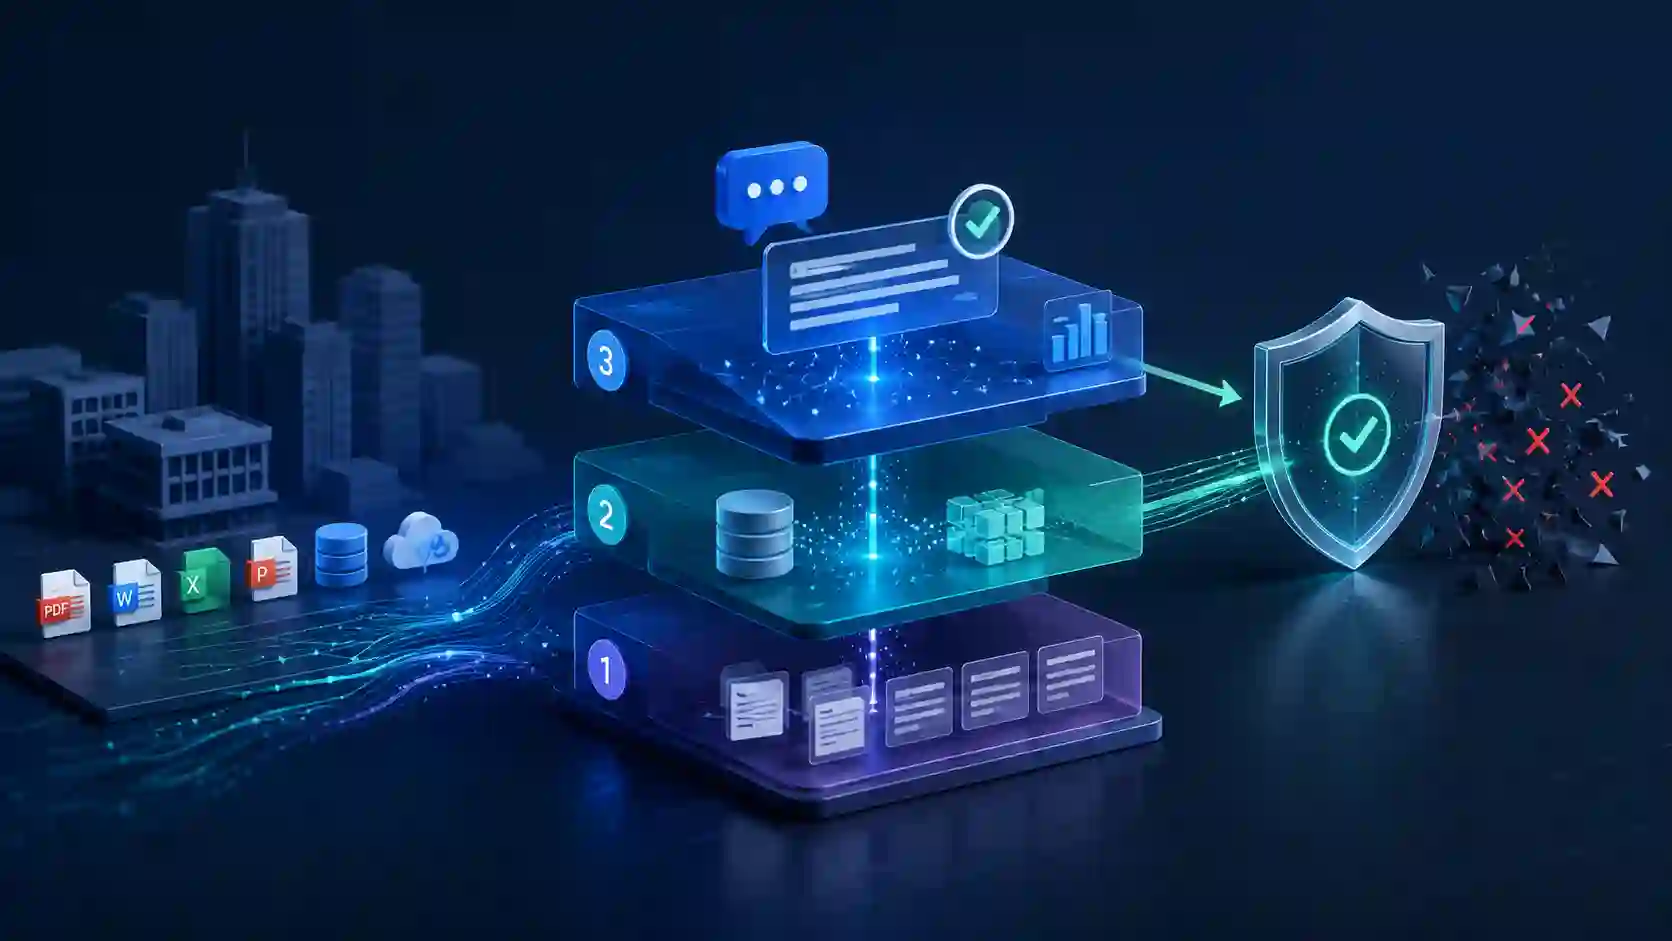
Short answer: You don't control RAG hallucination by swapping in a "smarter" model — you control it with operational architecture. On enterprise projects in Japan (insurance, public sector), I rely on a three-layer framework: gate the input, constrain the retrieval, and review the output. This reduces wrong-answer risk and makes failures traceable instead of hoping the model is "naturally smart enough."
TL;DR (Executive Summary)
- The problem: Deploying Custom RAG / AI chatbots for five major insurance groups and a public-sector AI project in Japan — where a single wrong answer (hallucination) isn't a minor bug but a legal and reputational risk (FSA compliance).
- The solution: A 3-Tier Review framework — input gating, retrieval grounding, and human-in-loop output review — instead of leaning on how "smart" the LLM is.
- The result: Materially lower customer-service operating costs while preserving enterprise-grade controls for accuracy and compliance throughout operation.
What is hallucination, really — from an operations standpoint?
Most articles define hallucination academically: "the model generates information that isn't true." Accurate, but useless when you're the one accountable for operations.
From a Delivery Manager / System Architect's seat, I redefine it: hallucination is when the system answers confidently about something it has no grounded data to assert. The core problem isn't that "the model makes things up" — it's that the system has no mechanism to admit "I don't know."
In an SME setting, a wrong answer might just annoy someone. In Japanese insurance, a chatbot that misstates a policy clause can trigger legal liability. These two problems are not in the same risk class, so they cannot share the same architecture.
Why doesn't "use a better model" solve it?
This is the most common trap. When the chatbot makes things up, the first instinct is "switch to a stronger model." But a stronger model just hallucinates more convincingly — it still doesn't know when to stay silent.
The real reason: most hallucination originates not in the generation step, but in retrieval. If the system retrieves the wrong document, or retrieves nothing yet still forces the model to answer, then even the most well-behaved model will fill the gap with a guess. This is why I always say: RAG is a data-architecture problem, not a model-selection problem.
The 3-Tier Review framework against hallucination
This is the framework I apply to enterprise Custom RAG systems. Each layer blocks a different class of error — and crucially, they are independent; no single layer carries all the responsibility.
Tier 1 — Input gating
Before a question ever reaches the LLM, the system classifies it: is this within scope of what the system is allowed to answer? Out-of-scope questions are blocked and redirected immediately — instead of letting the model strain to answer and then invent.
For unstructured data (contract PDFs, scanned documents), this tier also includes OCR + auto-screening: normalize the source documents and strip noise before indexing. Garbage in, garbage out — no model can rescue that.
Tier 2 — Retrieval grounding
This is the most important layer, and the one most often skipped. The principle: the model may only answer from retrieved documents, and must be able to cite the source. If retrieval returns a similarity below threshold (no sufficiently relevant document), the system is forced to answer "no information available" — rather than slipping into guess mode.
In other words, I design the system so it is allowed to say "I don't know." That is a feature, not a defect.
Tier 3 — Human-in-loop output review
In high-risk domains, not every answer fires straight to the customer. Answers touching sensitive territory (clauses, monetary figures, legal commitments) are routed through human review before sending. The bulk of frequently-asked questions stays fully automated to reduce load; only the "expensive" answers need a human.
This exact design — automate the cheap, keep humans on the expensive — is what materially reduced operating cost without trading away compliance controls.
Inside Tier 2: the 5-stage retrieval pipeline from chunking to eval
The 3-tier framework above answers where to control. This part goes one layer deeper: the retrieval engine underneath Tier 2. A Custom RAG that "works" is not decided at the model-selection step — it's decided in the retrieval pipeline: how you chunk documents, which model you embed with, whether you run hybrid search (vector + BM25), whether you rerank, and most importantly — what you measure it with. Most "RAG" on the market stops at a LangChain demo with none of these layers: it works on 5 pretty questions, clean documents, one language, and fabricates on scanned PDFs, clause tables, queries mixing Vietnamese and Japanese, or questions where the correct answer is "no information available." Below is the real pipeline I use for multilingual Vietnam–Japan RAG, with an eval table that has numbers.
The 5-stage pipeline — and the failure each stage closes
Stage 1 — Chunking: where most systems die quietly
The default approach — fixed 512-token cuts with overlap — destroys exactly the documents that need the most precision. A clause table cut mid-row loses its context; an 800-token clause split in half leaves no chunk with full meaning.
What I use is structure-aware chunking: cutting along the document's semantic boundaries — headings, articles/clauses, table-cell boundaries — not along a rigid token count. The goal: each chunk is a self-contained semantic unit, usually 300–500 tokens, with ~15% overlap to preserve boundary context. For tables I keep the row structure (row-aware) and attach column headers to each row, because users ask by row, not by isolated cell.
The rule I always repeat to the team: garbage that enters the index can't be saved by any reranker. Chunking is the cheapest layer but it sets the quality ceiling of the whole system.
Stage 2 — Embedding: a monolingual model is a trap in the Vietnam–Japan market
A Vietnamese question needs to retrieve a clause written in Japanese — this is a real situation, not a hypothetical. A monolingual embedding model (or one tuned for English) fails right here. I pick a multilingual embedding model that puts vi and ja in one shared vector space, so cross-lingual retrieval actually works.
A detail people skip: domain terminology. Insurance product names, business codes, internal abbreviations — generic embeddings misread them. I keep a glossary and handle these entities on both the index and the query side so they don't get semantically "mistranslated."
Stage 3 — Hybrid search: vector is strong on semantics, weak on exact match
This is the stage that separates demo RAG from production RAG. Vector search finds by meaning — excellent for paraphrased questions. But when a user types a contract number HD-2024-887 or a clause code 第12条, semantics is nearly useless; you need exact keyword match.
The solution is running two retrievers in parallel — dense (vector) + sparse (BM25) — then fusing them with Reciprocal Rank Fusion. Vector catches paraphrased questions, BM25 catches identifiers and rare terms. This stage alone is usually the biggest single recall jump in the whole pipeline.
Stage 4 — Reranking: separating "relevant enough" from "exactly right"
The retriever returns top-k fast but coarse. A cross-encoder reranker re-reads each (question, chunk) pair, scores true relevance, and narrows a coarse top-50 to a precise top-5. The difference: the retriever embeds question and chunk independently; the reranker looks at them together, so it catches nuance cosine similarity misses.
The cost is latency — reranking takes time. So I only rerank the coarse top-k (50), never the whole corpus. It's a trade-off I tune per project, like every other architectural decision.
Stage 5 — Eval: if you can't measure it, you don't own it
This is the stage that separates someone who operates RAG from someone who demos it. Without eval, every "improvement" is a feeling, and you never know whether a change made the system better or worse.
I build a golden set: a few hundred pairs of (question → correct source document → expected answer), including questions where the correct answer is "no information available." Then I measure with metrics that separate responsibility:
- Recall@k — is the correct document in the top-k retrieved? (measures the retrieval stage alone)
- Faithfulness / Groundedness — does the answer stay grounded in what was retrieved, with nothing invented? (measures the generation stage alone)
- Correct "I don't know" rate — when there's no source, does the system actually say "no information" instead of guessing?
The eval table: stacking each technique
This is the shape of the result I usually see as each stage is turned on against the same golden set. I don't give numbers: every document set lands at a different level, and a percentage table not tied to a specific project is easily read as a real measurement.
| Configuration | Metric that usually moves most | Failure class it closes |
|---|---|---|
| Naive (fixed chunk + vector only) | — (baseline) | — |
| + Structure-aware chunking | Recall@5, Faithfulness | Clauses and tables cut in half, so the retrieved passage misses part of the meaning |
| + Hybrid search (BM25) | Recall@5 | Codes, proper names and clause numbers that vector search misses |
| + Reranker | Faithfulness | Passages that are close in meaning but wrong pushing to the top |
What matters is the path: each stage closes a distinct class of failure, and you only know which stage is worth paying for when you have this table. A team quoting a RAG project that can't tell you what they'll measure with is usually a team that has never been accountable for a wrong answer in production.
What this RAG is NOT — so you don't buy the wrong thing
Let me be direct about expectations. This pipeline is optimized for accuracy over an enterprise document set (knowledge bases, contracts, internal procedures) at SME to mid-enterprise scale. It is not:
- A platform processing billions of vectors in real time — that's a different infrastructure problem needing a dedicated data-engineering team.
- A promise of "0% error, ever" — no system can promise that; what you buy is error that is controllable and measurable.
- An excuse to skip source-data quality — messy source documents mean messy results, and that's work to do before you talk about models.
If you're considering putting RAG into a process where a wrong answer has a real cost — and you want to work with someone who measures their system rather than just demos it — you can see more on AI Automation capabilities, read real project stories, or send a systems problem to discuss.
When do you NOT need this architecture?
I don't believe in forcing a heavy architecture onto every problem. This 3-tier framework is unnecessary if:
- You're building an internal lookup tool where a small mistake is harmless and there's no legal exposure.
- Question volume is low and manual review is still cheaper than building the pipeline.
- Your domain tolerates "approximately right" answers (e.g., content suggestions, brainstorming).
For those cases, a simple RAG — or no RAG at all — is the correct choice. I wrote about the trap of "burning money on AI in the wrong place" in Automation failures: the lessons.
The 3-tier architecture is for when a wrong answer has a real price — and that's exactly when it's worth every cent.
If you're weighing whether to put AI/RAG into a process where errors carry a real price — and you want someone who has owned the architecture of these systems end to end — you can explore my AI Automation capabilities, read real project case studies, or submit your system case to talk it through.
Nguyen Chau
Delivery Manager / System Architect
14 years architecting and operating systems for the Vietnam–Japan market
Frequently Asked Questions
Why doesn't a stronger model solve hallucination?
Because hallucination is an architecture problem, not a model-capability problem. A strong model still fabricates when nothing binds its answer to verified source data, so you need retrieval-control and validation layers.
When do you NOT need a 3-tier anti-hallucination architecture?
When small errors carry no serious consequences, such as a content-suggestion or general-info chatbot. The 3-tier design adds cost and latency and is only worth it when a wrong answer can create legal or financial risk.
Does RAG eliminate hallucination entirely?
No system guarantees an absolute 0%. But with a three-layer architecture — input gating, mandatory source-citing retrieval grounding, and human-in-loop on risky zones — you can push the risk to an enterprise-acceptable level and, more importantly, stay in control when it does occur (you can trace why).
Should I fine-tune a model or use RAG for enterprise data?
In most enterprise cases I've seen, RAG wins: the data changes constantly (updated clauses, new documents), re-fine-tuning is costly and hard to trace. RAG lets you update knowledge by updating the index, and always cite a source — a hard requirement when compliance is involved.
Where does the biggest cost of building enterprise Custom RAG actually sit?
Not in the model or infrastructure — in normalizing the source data (Tier 1) and designing thresholds and review flows (Tiers 2–3). This is the "unsexy" part that decides whether the system lives or dies. A vendor whose quote only prices the model usually hasn't operated a real RAG system in a demanding environment. The retrieval engine underneath — chunking, hybrid search, reranking, and an eval table with numbers — is opened up in the 5-stage pipeline section of this post.
What is the single most important metric for evaluating a RAG system?
Retrieval recall (Recall@k) and faithfulness/groundedness — not "the answer sounds good." Recall@k measures whether the correct document is in the top-k retrieved; faithfulness measures whether the answer stays grounded in what was retrieved. If retrieval is wrong, everything downstream is wrong.
When do you need hybrid search instead of pure vector search?
When queries contain exact identifiers — contract numbers, clause codes, product codes. Vector search is strong on semantics but weak on exact match; adding BM25 (sparse) and fusing the results catches both kinds of query.
Which vector DB should I use?
The correct answer is "it depends on scale," not "whichever is hottest." At SME scale, a Postgres with pgvector is usually enough and simple to operate. As vector count and latency requirements grow, a dedicated vector DB (Qdrant, Milvus...) starts to earn its extra operational cost. Choosing a vector DB before you know the scale is putting the cart before the horse.